Storage Requirements
This section outlines the key storage requirements for the components used by Omnia to deploy HPC clusters. For more information about the supported devices and software, see Support Matrix.
NFS Server
-
If PowerScale is configured as the NFS server using NFSv4 protocol, the following settings must be enabled on the PowerScale cluster to prevent file ownership from displaying as
nobody:nobody:From the PowerScale web interface, navigate to Protocols > NFS > Zone settings and enable:
nfsv4-no-names = truenfsv4-no-domain = truenfsv4-no-domain-uids = truenfsv4-allow-numeric-ids = true
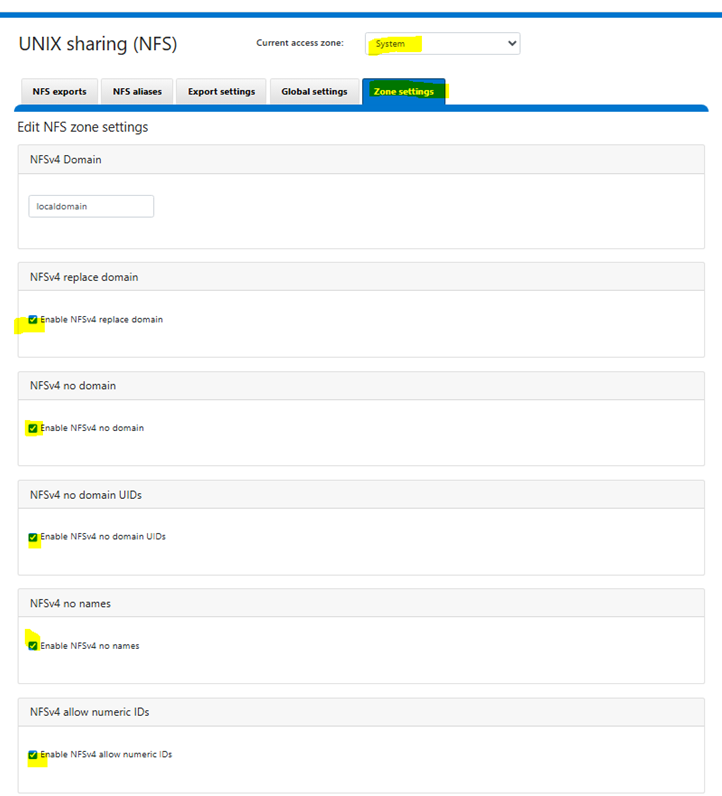
Alternatively, run the following CLI command:
Run on: PowerScale clusterisi nfs settings zone modify \ --nfsv4-no-names=true \ --nfsv4-no-domain=true \ --nfsv4-no-domain-uids=true \ --nfsv4-allow-numeric-ids=true \ --zone=SystemThis configuration ensures the following:
- PowerScale sends numeric UIDs/GIDs instead of string-based identity (
user@domain), which eliminates thenobody:nobodyownership issue caused by NFSv4 domain mismatch. - Ensure that UID/GID mappings are consistent across all NFS client nodes and the PowerScale cluster. Since numeric ID mode bypasses name-based identity resolution, mismatched UIDs/GIDs between clients will result in incorrect file ownership.
- This setting degrades NFSv4 ACL support. If your environment requires NFSv4 ACLs, consider aligning the NFSv4 domain between PowerScale and all clients instead.
- For more details, see Dell KB 000023023.
-
Choose an NFS server located outside your cluster.
- The NFS share has 755 permissions and
no_root_squashis enabled during mount. -
To enable
no_root_squash, edit the/etc/exportsfile on the NFS server and include the option for the exported path, run the following command:File: /etc/exports/<your_exported_path> *(rw,sync,no_root_squash,no_subtree_check) -
Ensure that the external NFS share is accessible from all nodes (both diskless and diskful) and is reachable via the admin network.
NFS Server for K8s
- Minimum NFS for Kubernetes is 200 GB. The storage is recommended based on small cluster deployments. Increase the storage based on cluster size and telemetry data.
- Ensure that there is a dedicated mount point for each NFS.
NFS Server for Slurm
- Minimum NFS for Slurm is 50 GB. Increase the storage based on cluster size and job data volume.
- If GPU nodes are present and CUDA toolkit will be shared via NFS, allocate an additional 30 GB for the
/hpc_tools/cudapath. - Ensure that there is a dedicated mount point for each NFS.
- The NFS share is used by Omnia to store and distribute Slurm configuration files (
slurm.conf,slurmdbd.conf,cgroup.conf,gres.conf), munge authentication keys, and shared state directories across all Slurm nodes. - The OIM must have write access to this share during provisioning (
mount_on_oim: trueinstorage_config.yml). - The NFS share must be reachable from all Slurm controller, compute, and login nodes at boot time.
VAST Storage for Slurm (Optional)
- If a dedicated VAST storage appliance is available, it can be configured as the HPC tools and benchmark storage backend via the
vast_storage_nameparameter inomnia_config.yml. - VAST with RDMA transport provides lower latency and higher throughput compared to standard NFS, which benefits latency-sensitive HPC workloads.
- RDMA transport requires InfiniBand or RoCE connectivity between cluster nodes and the VAST appliance.
- If
vast_storage_nameis not specified, Omnia uses the primary NFS mount (nfs_storage_name) for HPC tools storage. - For VAST appliance setup, see Configure VAST Storage.
For details on how Slurm uses these mounts, see Slurm Storage Architecture.
NFS Server for Omnia Infrastructure Manager (OIM)
- Omnia recommends using an NFS share with at least 200 GB storage for OIM and cluster configuration.
- Ensure that there is a dedicated mount point for each NFS.
PowerScale S3 Storage
- PowerScale can be selected as the external S3 backend in Image Build Manager. Its endpoint must be reachable from the OIM and from target nodes while they download boot artifacts during PXE boot.
- The configured
endpoint_urlcan use HTTP or HTTPS. Ensure the endpoint's actual port and certificate trust configuration match the site deployment. - Provide the S3 access ID and secret key through the Image Build Manager
credentials flow. These values are stored in its Vault-encrypted credential
file rather than
storage_config.yml. - Configure
s3_configurations.provider: "powerscale"and the endpoint inimage_build_config.yml. For appliance-side setup, see Configure PowerScale as S3 storage.
Info
- Storage Config -- NFS, PowerVault, swap, and mount configuration.
- Image Build Config -- S3 provider and endpoint configuration.